A reproducible comparison
How the ASS works
- 01
Set a fixed brief
Every model receives the same real-world task and constraints.
- 02
Run without re-rolls
Temperature zero and a sandboxed workflow keep every attempt comparable.
- 03
Compare the trade-offs
Review quality, cost and latency together—not a vendor-picked benchmark.
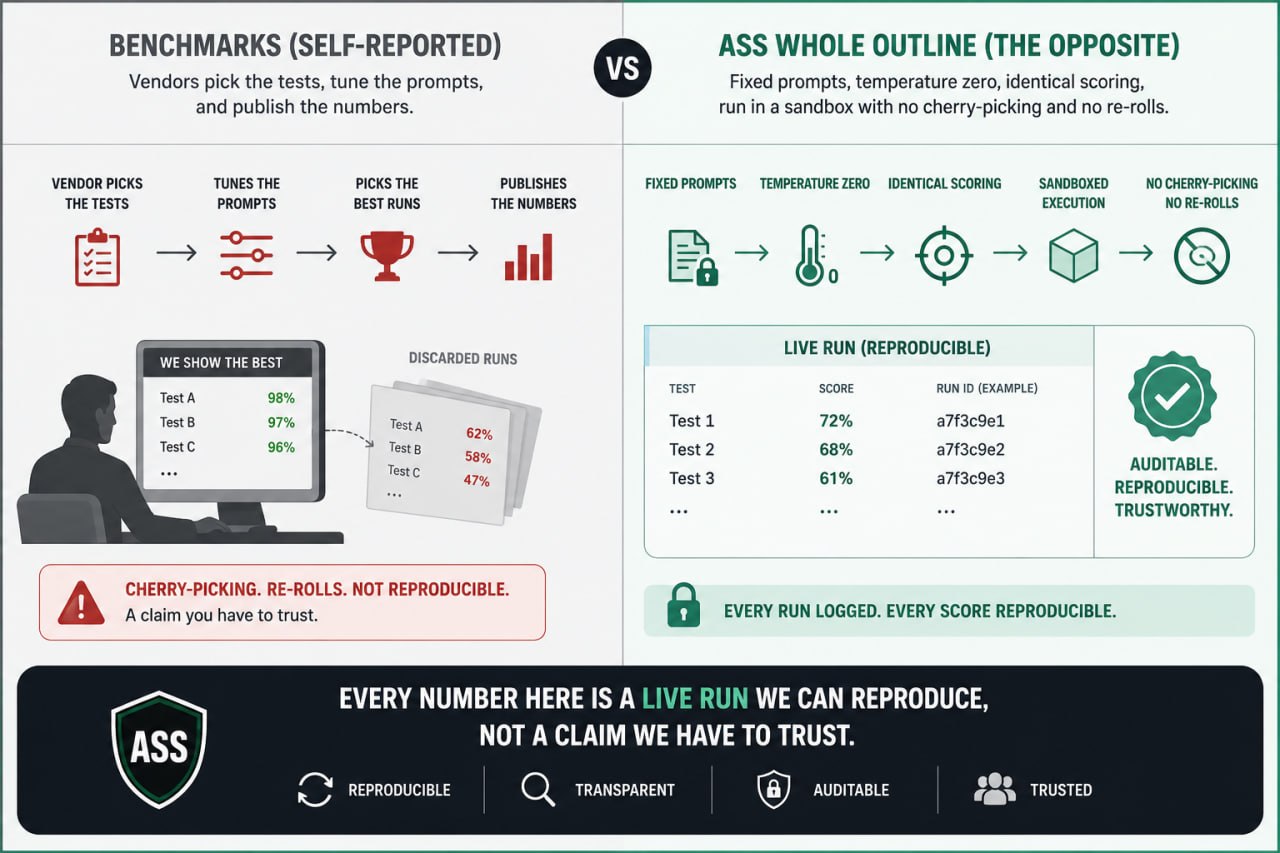
Why not benchmarks?
Benchmarks are self-reported — vendors pick the tests, tune the prompts, and publish the numbers. The ASS Whole Outline is the opposite: fixed prompts, temperature zero, identical scoring, run in a sandbox with no cherry-picking and no re-rolls. Every number here is a live run we can reproduce, not a claim we have to trust.